Why The Times performs so well in Google Discover

A data and technical analysis based on a year of Discover mentions (UK) and live research
TL;DR | Key findings
Methodology: analysis based on a DiscoverSnoop export for the UK (1,721 Discover mentions, July 29, 2025 – July 28, 2026, approx. 70% of the total Discover volume of The Times), supplemented by live research.
Why this research?
The impetus for this research was an article by Press Gazette highlighting that The Times achieves strong year-on-year results. That made me curious: what exactly is this title doing right, and can it be traced back to specific choices in content, technology, or strategy? Instead of just noting that things are going well, I wanted to find out where that success comes from, with Google Discover as one of the measurable channels through which that success becomes visible.
Research methodology
For this research, I followed these steps:
- Used a DiscoverSnoop export containing all Discover mentions for The Times (UK) over the past twelve months.
- Converted this raw export into clear tables and actionable data points using Claude (Anthropic), such as monthly volumes, category distributions, and entity analyses.
- Conducted a manual audit based on that data: I personally reviewed and checked individual articles, the robots.txt, structured data, paywall structure, and subscription offers live to verify if the patterns from the data were actually reflected on the site itself.
- The final, continuous text of this article was shaped into a coherent story with the help of Claude, based on my own analysis and findings.
1. Volume and growth: a rising trend, not a fluke
August 2025 is the first month with full coverage in the export and serves as the baseline (July 2025 was a partial month and was therefore excluded):
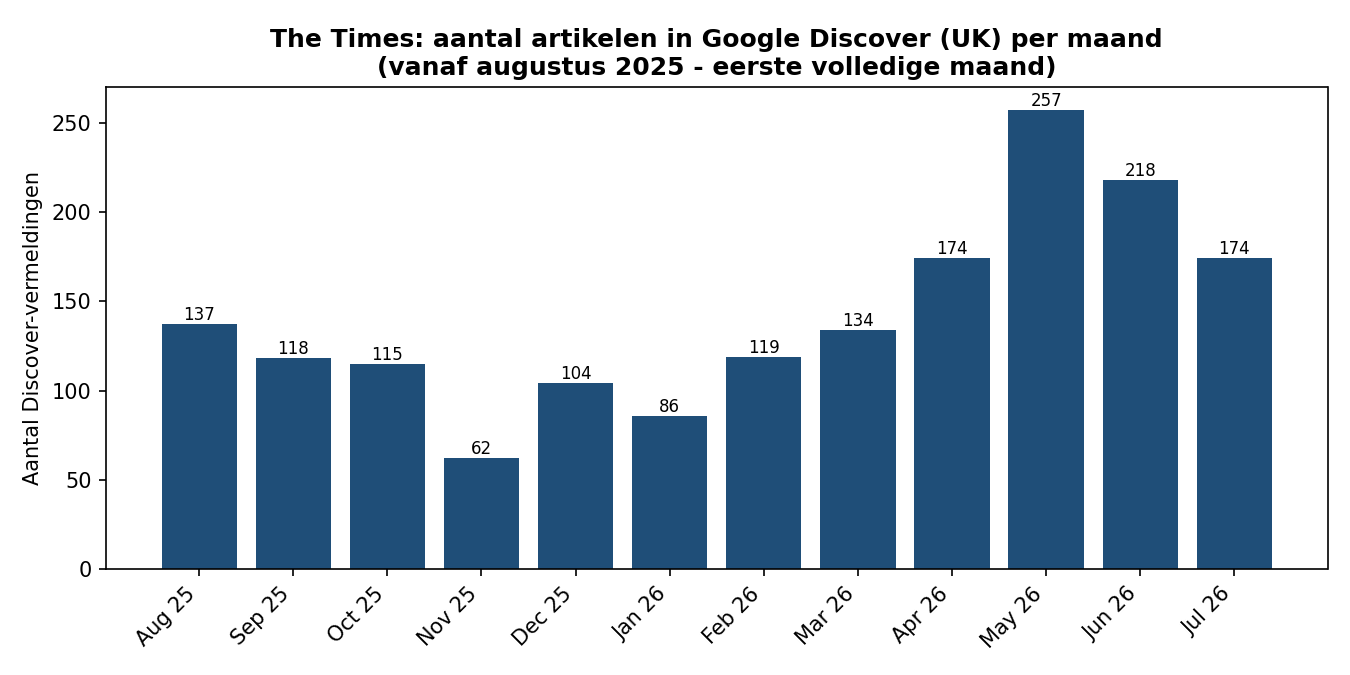
From this starting point (137 in August 2025), the trend rises to a peak of 257 in May 2026. This represents growth of approximately 87%, largely gradual from January 2026, with a temporary dip in November 2025 (62). The slightly lower figures in June/July 2026 remain well above the levels of a year earlier. For a subscription site, this is a deliberate investment: Discover traffic typically does not convert directly into subscribers, so the value lies primarily in brand awareness and top-of-funnel reach.
2. Content mix: human drama and royals beat dry news
The DiscoverSnoop category breakdown shows where the volume originates:
|
Category |
Number of mentions |
|---|---|
|
Sensitive Subjects |
99 |
|
Law & Government / Government |
84 |
|
News (general) |
76 |
|
Celebrities & Entertainment News |
69 |
|
News / Politics |
60 |
|
Travel / Air Travel |
40 |
|
Soccer |
39 |
However, when looking at the top-performing individual articles, a pattern emerges: concrete, individual stories with a recognizable protagonist, an amount, or an explicit dilemma. Some examples from the top 20 of the dataset:
The entity analysis confirms this at a larger scale: after ‘Sport’ and ‘Scotland’, ‘British royal family’, ‘Prince of Wales’ and ‘Duke of York’/’Prince Andrew’ are the most frequent entities. This points to a steady, high-frequency ‘safe bet’ content line alongside the occasional human-interest outliers above.
3. Editorial strength: EEAT, transparency, and no distractions
Beyond the Discover figures, several structural choices stand out that strengthen the site, both for user experience and for trust signals toward Google and readers.
Author profiles with specific roles
Bylines mention not just a name, but a job title. For example, a live blog about the Prime Minister’s social care speech featured three authors with explicit roles: ‘Daisy Eastlake, Political Reporter’, ‘Eleanor Hayward, Health Editor’, and ‘Ben Clatworthy, Whitehall Editor’. Each name links to a profile page with a photo, job title, social handle, and a beat description that goes beyond a generic bio:
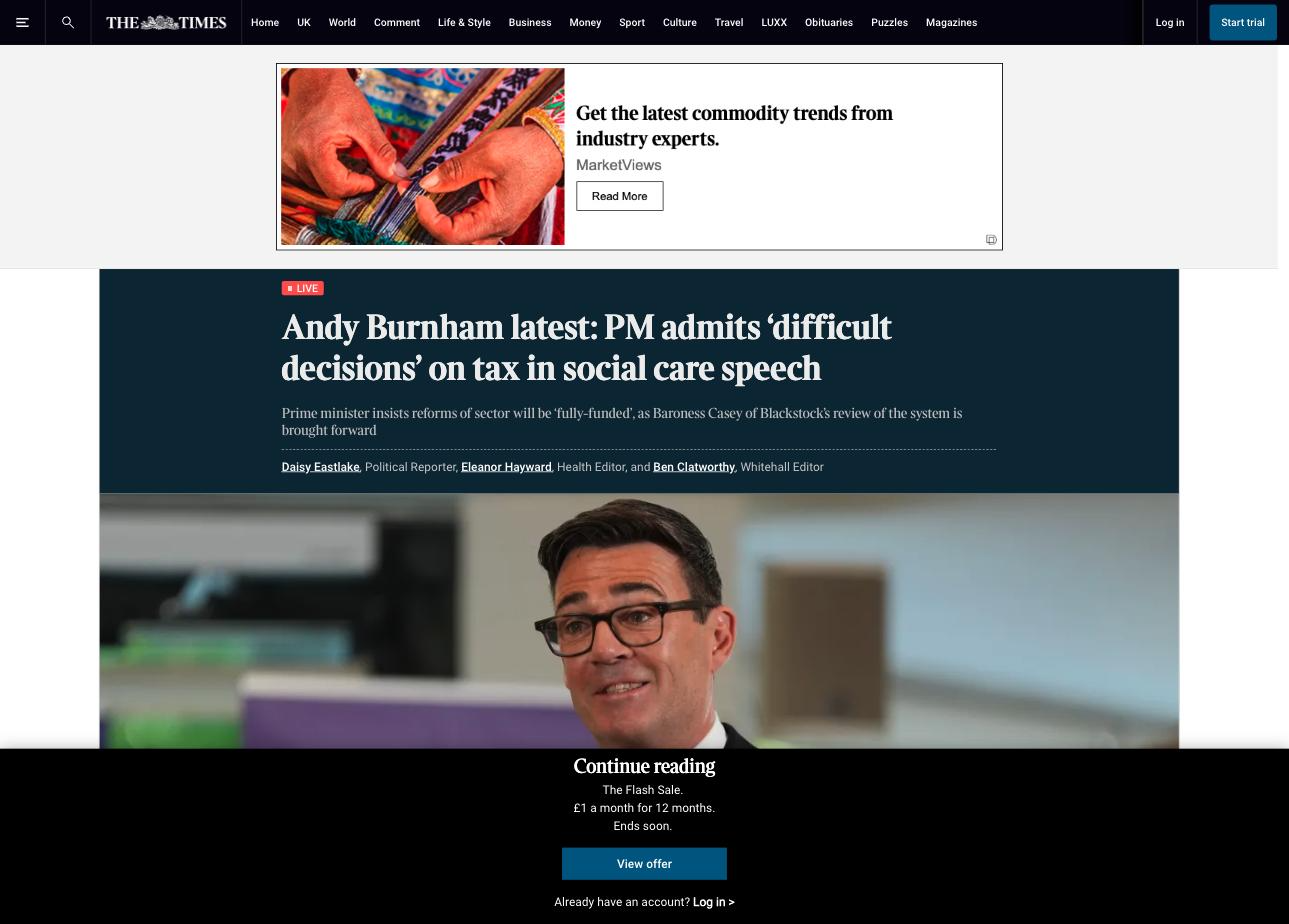
Live blog article: LIVE badge, three authors with job titles in the byline.
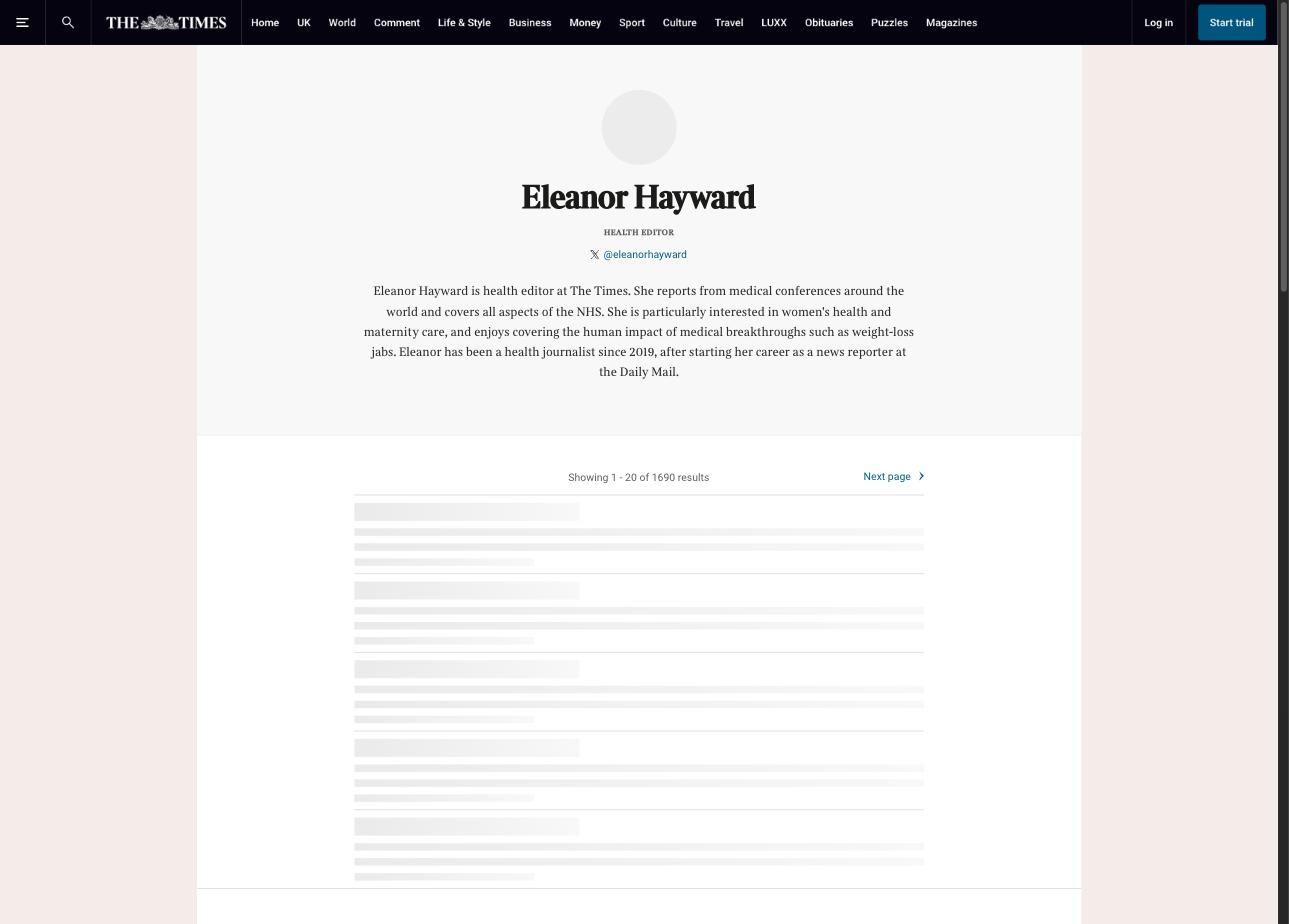
Eleanor Hayward profile page: role, beat description, social link, and archive of 1,690 articles.
Live content is unmistakably labeled
Both on the homepage teaser and the article page itself, there is a red ‘LIVE’ badge, clearly visually distinguished from regular articles (dark background instead of white). Under the hood, this corresponds to a separate schema type: alongside NewsArticle and BreadcrumbList, we found LiveBlogPosting for this live blog article. This is the correct, specific schema for this content type instead of generic NewsArticle markup.
No overlay ads
None of the seven researched article pages or the homepage featured an interstitial, popup, or overlay ad blocking the content. Only standard banner ads appeared above the fold. For a site with this ad volume, this is a deliberate choice that benefits the reading experience (and thus page experience signals).
Puzzle section as a separate retention engine
Independent of news and Discover, The Times has an extensive, daily refreshed puzzles section (crosswords, sudokus, word and logic puzzles, board games). This type of content does not generate Discover traffic but provides a reason to return directly to the site daily. This creates a complementary retention strategy alongside the Discover-dependent inflow of news articles.
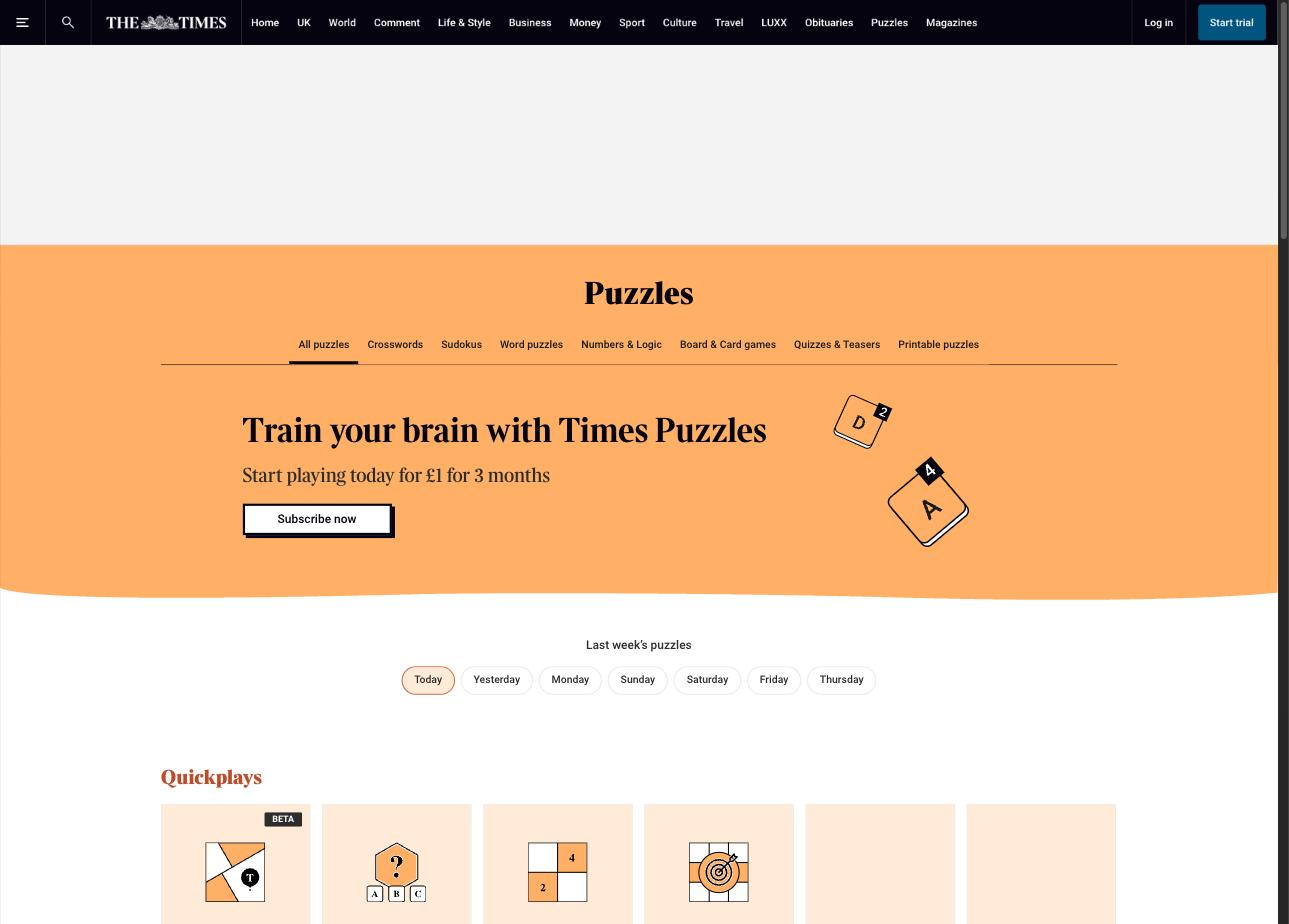
A layered, low-threshold subscription offer
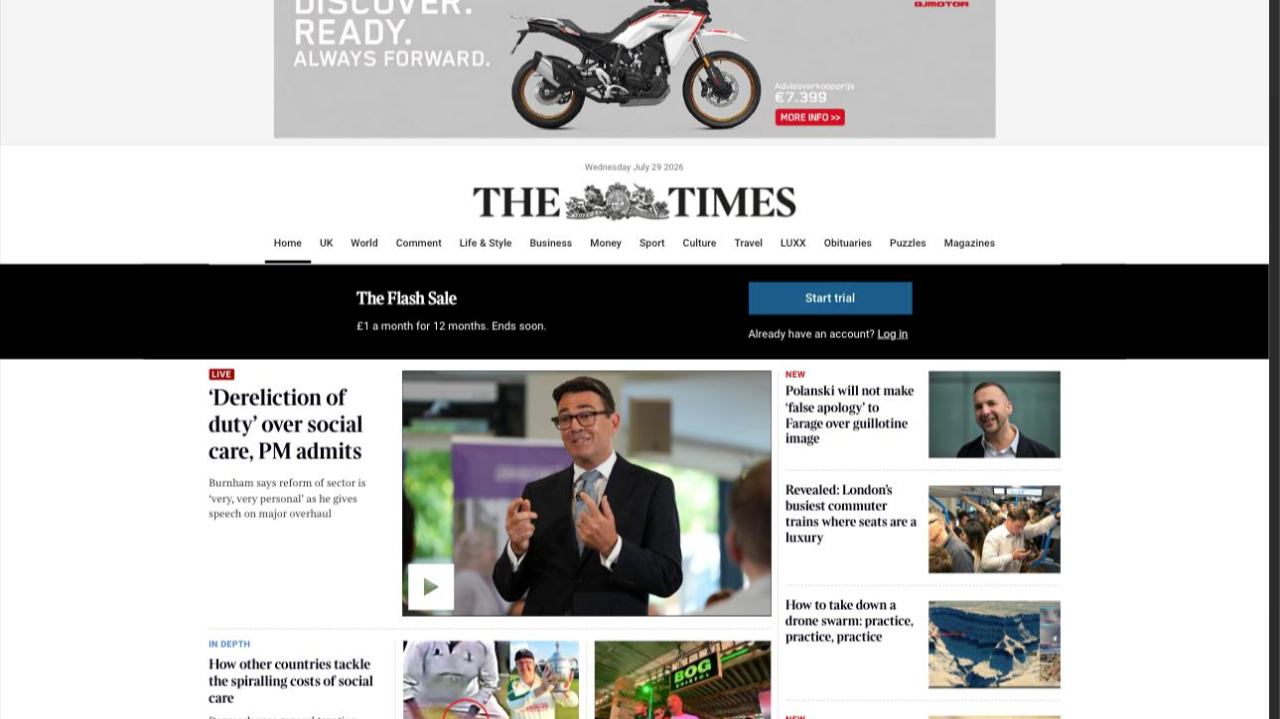
Notably, there are two different introductory offers existing side-by-side: the site-wide ‘Flash Sale’ offer (£1 per month for 12 months, visible in the banner on every paywalled page) and a separate, even lower introductory offer specifically for the Puzzles section (£1 for 3 months). This is deliberate segmentation: visitors arriving via a news article see a different offer than those coming primarily for puzzles.
4. Freshness and URL strategy: how articles return to Discover
Across seven measurements (six articles, spread over several months and content types), an article typically appears in Discover between 1.8 and 11.1 hours after publication. So, the same day to the following morning, never days later, with one significant exception highlighted below.
The strongest and most concrete evidence in this dataset for deliberate content recirculation is the Dragons’ Den/Vitabiotics article. This article was initially located at:
Live research confirms: this old URL now provides a 301 redirect to a new section URL with the same slug:
The article thus moved from the ‘economics’ section to ‘companies-markets’, an editorial reclassification as the story developed (from macro-economic news to a specific corporate deal), and received a clean redirect instead of a dead link or duplicate content. Two days after the original publication (dateModified shifted from May 30 to June 1), the article returned to Discover under the new URL as a separate mention with its own score (5.9). This is a concrete, repeatable mechanism: a visible section/URL migration with correct redirect and canonical can make an article Discover-worthy again, rather than it quietly disappearing from circulation.
5. Technology: schema and crawler governance
At the page level, the technical setup is functional and without redundant additions: standard articles contain two JSON-LD blocks (NewsArticle + BreadcrumbList), live blogs a third (LiveBlogPosting). No schema stacking, no redundant FAQ or HowTo markup that doesn’t fit the content type.
More interesting is the robots.txt. The Times blocks all crawlers by default (‘Disallow: /’ for User-agent: *), but explicitly waives this for a long, specifically curated list: Googlebot, Bingbot, DuckDuckBot, and Applebot alongside SEO tools (Screaming Frog, SemrushBot, OnCrawl) and notably GPTBot, ChatGPT-User, and OAI-SearchBot. The explanation in the file itself is explicit: ‘The Times does not permit the unlicensed use of our content for large language models.’ This implies that the crawlers that are allowed access do so based on a licensing agreement—not a blanket ban, but targeted access control per party.

The Google News sitemap confirms the publication speed: at the time of research, the sitemap contained 337 articles within a window of approximately 48 hours—averaging about 168 new or updated articles per day site-wide.
6. Paywall and headline strategy: the title must sell twice
When visiting an article page, the content is gated almost immediately: the headline and a one-sentence lead-in are followed straight away by the subscription block.
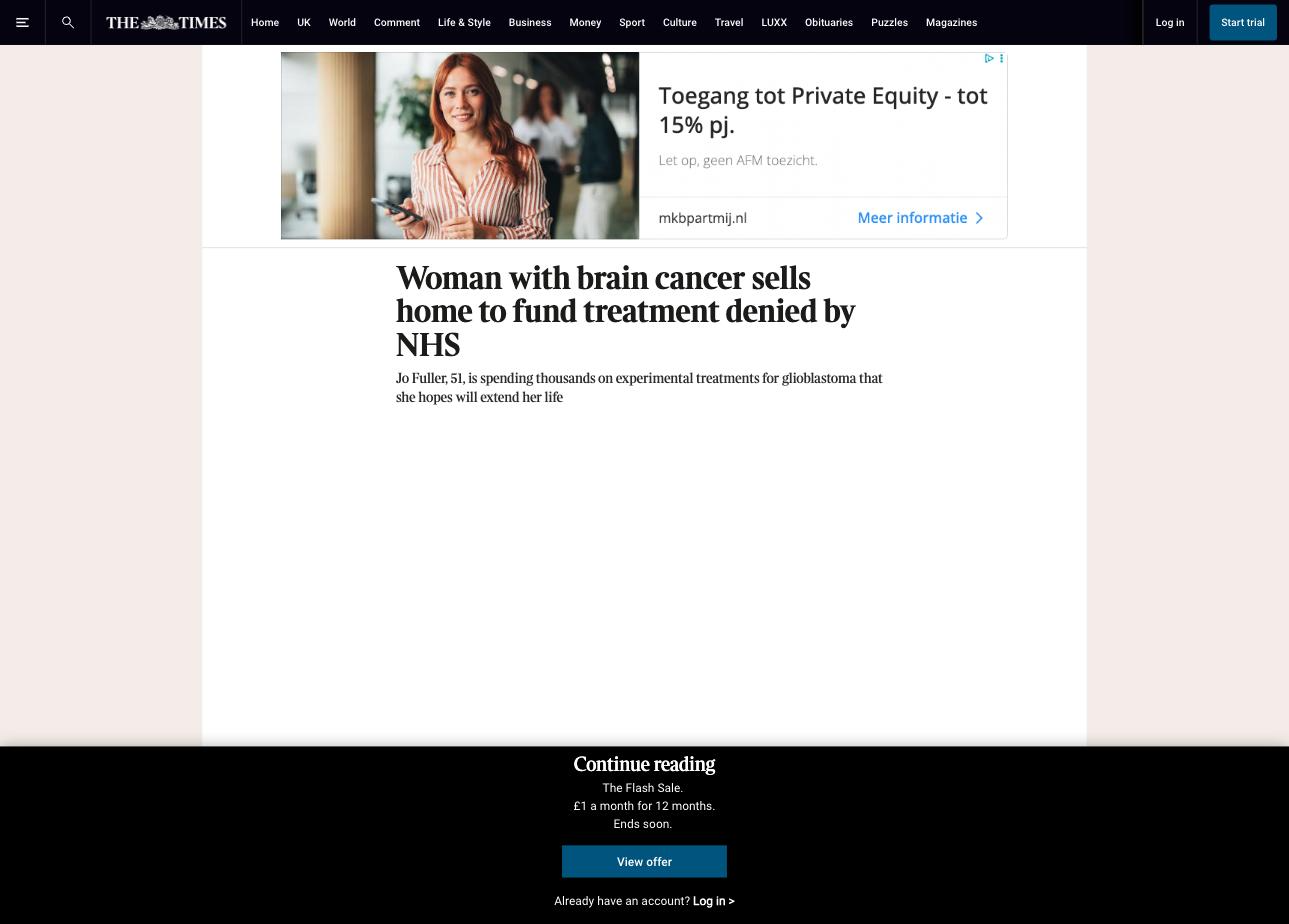
Article page directly behind the cookie wall: headline and standfirst are the only freely visible text elements
This means that the title and standfirst play a dual role: they must earn the Discover click and generate the curiosity that leads to a trial subscription. This partly explains why many top-scoring headlines are constructed around a specific person, a specific amount, or a specific outcome. Specificity works both as a Discover hook and a conversion incentive.
Concrete advice for publishers
The advice below is directly derived from the findings above and is generically applicable to other news or content sites, not just The Times itself.
Disclaimer: Claude was used for data extraction from the DiscoverSnoop export and for processing my findings into a continuous narrative. Analysis, interpretation, and conclusions are based on my own manual checks performed on The Times website.